rs_knit_coordsets_demo
Combine coordinate sets with partially overlapping stimuli
calculates statistics, without and with scaling allowed between datasets plots both sets of stats on same figure , adjusting dataset and stimulus names
See also: rs_knit_coordsets, rs_align_coordsets
=;
=;
=;Output:
Enter pipeline display verbosity (range: 0 to 2, default= 0):0
Enter 1 to write the knitted sets (range: 0 to 1):0
Enter number of shuffles for statistics (0 for none) (range: 0 to 1000, default= 10):10
section to force btc defaults, even if rs_aux_defaults.mat has been created or modified
=struct;
={};
={};
=;
=auxs_force;
=nsets;
=1;
=;
=1;read the data
[]=;Output:
 entering set  1 of  3:
primary dataset 1 is experimental data
 25 different stimulus types found in  data file ./samples/bwtextures/bgca3pt_coords_MC_sess01_10.mat
suggested ray permutation for bgca:
     2     1     3     4

 25 different stimulus types found in setup file ./samples/bwtextures/bgca3pt9.mat
 25 of  25 labels found
coordinate sets with  1 to  7 dimensions read.

 entering set  2 of  3:
primary dataset 2 is experimental data
 25 different stimulus types found in  data file ./samples/bwtextures/bdce3pt_coords_MC_sess01_10.mat
suggested ray permutation for bdce:
     1     3     2     4

 25 different stimulus types found in setup file ./samples/bwtextures/bdce3pt9.mat
 25 of  25 labels found
coordinate sets with  1 to  7 dimensions read.
warning: the following stimulus type names do not match in dataset 2 (primary: 2):
   for stim   4, expecting               gp0133 found               dp0200 , stim not present at all
   for stim   5, expecting               gp0267 found               dp0400 , stim not present at all
   for stim   6, expecting               gp0400 found               dp0600 , stim not present at all
   for stim  10, expecting               ap0333 found               ep0200 , stim not present at all
   for stim  11, expecting               ap0667 found               ep0400 , stim not present at all
   for stim  12, expecting               ap1000 found               ep0600 , stim not present at all
   for stim  16, expecting               gm0133 found               dm0200 , stim not present at all
   for stim  17, expecting               gm0267 found               dm0400 , stim not present at all
   for stim  18, expecting               gm0400 found               dm0600 , stim not present at all
   for stim  22, expecting               am0333 found               em0200 , stim not present at all
   for stim  23, expecting               am0667 found               em0400 , stim not present at all
   for stim  24, expecting               am1000 found               em0600 , stim not present at all

 entering set  3 of  3:
primary dataset 3 is experimental data
 25 different stimulus types found in  data file ./samples/bwtextures/dgea3pt_coords_MC_sess01_10.mat
suggested ray permutation for dgea:
     2     1     3     4

 25 different stimulus types found in setup file ./samples/bwtextures/dgea3pt9.mat
 25 of  25 labels found
coordinate sets with  1 to  7 dimensions read.
warning: the following stimulus type names do not match in dataset 3 (primary: 3):
   for stim   1, expecting               bp0200 found               dp0200 , stim not present at all
   for stim   2, expecting               bp0400 found               dp0400 , stim not present at all
   for stim   3, expecting               bp0600 found               dp0600 , stim not present at all
   for stim   7, expecting               cp0200 found               ep0200 , stim not present at all
   for stim   8, expecting               cp0400 found               ep0400 , stim not present at all
   for stim   9, expecting               cp0600 found               ep0600 , stim not present at all
   for stim  13, expecting               bm0200 found               dm0200 , stim not present at all
   for stim  14, expecting               bm0400 found               dm0400 , stim not present at all
   for stim  15, expecting               bm0600 found               dm0600 , stim not present at all
   for stim  19, expecting               cm0200 found               em0200 , stim not present at all
   for stim  20, expecting               cm0400 found               em0400 , stim not present at all
   for stim  21, expecting               cm0600 found               em0600 , stim not present at all

datasets selected:
 set  1: dim range [  1   7] label: samples/bwtextures/bgca3pt_MC_sess01_10
 set  2: dim range [  1   7] label: samples/bwtextures/bdce3pt_MC_sess01_10
 set  3: dim range [  1   7] label: samples/bwtextures/dgea3pt_MC_sess01_10
align
[]=;Output:
 set   1: simplification attempted,   0 coords simplified (label: samples/bwtextures/bgca3pt_MC_sess01_10)
 set   2: simplification attempted,   0 coords simplified (label: samples/bwtextures/bdce3pt_MC_sess01_10)
 set   3: simplification attempted,   0 coords simplified (label: samples/bwtextures/dgea3pt_MC_sess01_10)
proceeding with alignment of   3 datasets, paradigm type btc, stimuli must be present in 1
alignments attempted with  3 datasets
 set   1: stimuli:  25, type       data, label samples/bwtextures/bgca3pt_MC_sess01_10
 set   2: stimuli:  25, type       data, label samples/bwtextures/bdce3pt_MC_sess01_10
 set   3: stimuli:  25, type       data, label samples/bwtextures/dgea3pt_MC_sess01_10
 unique typenames:  37
 typenames present in at least  1 datasets:  37
if_type_coords_remake=0 (determined from metadata)
knit
[]=;Output:
 number of stimuli missing in dataset   1:   12
 number of stimuli missing in dataset   2:   12
 number of stimuli missing in dataset   3:   12
data table
    25    13    13
    13    25    13
    13    13    25

sa_pooled and data_align will be created.
NaN removal attempted with  3 datasets
 set   1: stimuli:  37, type       data, label samples/bwtextures/bgca3pt_MC_sess01_10
 set   2: stimuli:  37, type       data, label samples/bwtextures/bdce3pt_MC_sess01_10
 set   3: stimuli:  37, type       data, label samples/bwtextures/dgea3pt_MC_sess01_10
 unique typenames:  37
 set   1: simplification attempted,   0 coords simplified (label: samples/bwtextures/bgca3pt_MC_sess01_10)
 set   2: simplification attempted,   0 coords simplified (label: samples/bwtextures/bdce3pt_MC_sess01_10)
 set   3: simplification attempted,   0 coords simplified (label: samples/bwtextures/dgea3pt_MC_sess01_10)
proceeding with alignment of   3 datasets, paradigm type btc, stimuli must be present in 1
alignments attempted with  3 datasets
 set   1: stimuli:  25, type       data, label samples/bwtextures/bgca3pt_MC_sess01_10
 set   2: stimuli:  25, type       data, label samples/bwtextures/bdce3pt_MC_sess01_10
 set   3: stimuli:  25, type       data, label samples/bwtextures/dgea3pt_MC_sess01_10
 unique typenames:  37
 typenames present in at least  1 datasets:  37
if_type_coords_remake=0 (determined from metadata)
knitting  37 stimuli across   3 datasets, dimensions   1  2  3  4  5  6  7
  allow reflection: 1, allow offset: 1, allow scale: 0, normalize scale: 0, rotate to pcs: 0
 calculations with allow_scale=0, if_normscale=0
 set  1: created shuffles for  25 stimuli
 set  2: created shuffles for  25 stimuli
 set  3: created shuffles for  25 stimuli
 creating Procrustes consensus from dim  1 to dim  1 based on component datasets, iterations:    8, final total rms dev per coordinate:  1.05588
 creating Procrustes consensus from dim  2 to dim  2 based on component datasets, iterations:   12, final total rms dev per coordinate:  0.44757
 creating Procrustes consensus from dim  3 to dim  3 based on component datasets, iterations:   14, final total rms dev per coordinate:  0.39385
 creating Procrustes consensus from dim  4 to dim  4 based on component datasets, iterations:   24, final total rms dev per coordinate:  0.39563
 creating Procrustes consensus from dim  5 to dim  5 based on component datasets, iterations:   28, final total rms dev per coordinate:  0.37277
 creating Procrustes consensus from dim  6 to dim  6 based on component datasets, iterations:  136, final total rms dev per coordinate:  0.38140
 creating Procrustes consensus from dim  7 to dim  7 based on component datasets, iterations:  255, final total rms dev per coordinate:  0.37534
also knit with allowing a scaling between datasets
=aux;
=1;
=1;
[]=;Output:
 number of stimuli missing in dataset   1:   12
 number of stimuli missing in dataset   2:   12
 number of stimuli missing in dataset   3:   12
data table
    25    13    13
    13    25    13
    13    13    25

sa_pooled and data_align will be created.
NaN removal attempted with  3 datasets
 set   1: stimuli:  37, type       data, label samples/bwtextures/bgca3pt_MC_sess01_10
 set   2: stimuli:  37, type       data, label samples/bwtextures/bdce3pt_MC_sess01_10
 set   3: stimuli:  37, type       data, label samples/bwtextures/dgea3pt_MC_sess01_10
 unique typenames:  37
 set   1: simplification attempted,   0 coords simplified (label: samples/bwtextures/bgca3pt_MC_sess01_10)
 set   2: simplification attempted,   0 coords simplified (label: samples/bwtextures/bdce3pt_MC_sess01_10)
 set   3: simplification attempted,   0 coords simplified (label: samples/bwtextures/dgea3pt_MC_sess01_10)
proceeding with alignment of   3 datasets, paradigm type btc, stimuli must be present in 1
alignments attempted with  3 datasets
 set   1: stimuli:  25, type       data, label samples/bwtextures/bgca3pt_MC_sess01_10
 set   2: stimuli:  25, type       data, label samples/bwtextures/bdce3pt_MC_sess01_10
 set   3: stimuli:  25, type       data, label samples/bwtextures/dgea3pt_MC_sess01_10
 unique typenames:  37
 typenames present in at least  1 datasets:  37
if_type_coords_remake=0 (determined from metadata)
knitting  37 stimuli across   3 datasets, dimensions   1  2  3  4  5  6  7
  allow reflection: 1, allow offset: 1, allow scale: 1, normalize scale: 1, rotate to pcs: 0
 calculations with allow_scale=1, if_normscale=1
 set  1: created shuffles for  25 stimuli
 set  2: created shuffles for  25 stimuli
 set  3: created shuffles for  25 stimuli
 creating Procrustes consensus from dim  1 to dim  1 based on component datasets, iterations:   65, final total rms dev per coordinate:  0.95566
 creating Procrustes consensus from dim  2 to dim  2 based on component datasets, iterations:   14, final total rms dev per coordinate:  0.44842
 creating Procrustes consensus from dim  3 to dim  3 based on component datasets, iterations:   15, final total rms dev per coordinate:  0.39404
 creating Procrustes consensus from dim  4 to dim  4 based on component datasets, iterations:   23, final total rms dev per coordinate:  0.39562
 creating Procrustes consensus from dim  5 to dim  5 based on component datasets, iterations:   23, final total rms dev per coordinate:  0.37207
 creating Procrustes consensus from dim  6 to dim  6 based on component datasets, iterations:  121, final total rms dev per coordinate:  0.37976
 creating Procrustes consensus from dim  7 to dim  7 based on component datasets, iterations:  220, final total rms dev per coordinate:  0.37148
show pipelines, also expanding the contents of sets and sets_combined
;
;
;
;Output:
%%%%%%%%%%%%%%%%%%%
pipeline for knitted dataset, no scaling
 depth 0, type knit

examining pipeline at depth 1 of sets_combined: entry  1 of  3
      depth 1, type align
     examining pipeline at depth 2 of sets: entry  1 of  1-> empty
     examining pipeline at depth 2 of sets_combined: entry  1 of  3-> empty
     examining pipeline at depth 2 of sets_combined: entry  2 of  3-> empty
     examining pipeline at depth 2 of sets_combined: entry  3 of  3-> empty

examining pipeline at depth 1 of sets_combined: entry  2 of  3
      depth 1, type align
     examining pipeline at depth 2 of sets: entry  1 of  1-> empty
     examining pipeline at depth 2 of sets_combined: entry  1 of  3-> empty
     examining pipeline at depth 2 of sets_combined: entry  2 of  3-> empty
     examining pipeline at depth 2 of sets_combined: entry  3 of  3-> empty

examining pipeline at depth 1 of sets_combined: entry  3 of  3
      depth 1, type align
     examining pipeline at depth 2 of sets: entry  1 of  1-> empty
     examining pipeline at depth 2 of sets_combined: entry  1 of  3-> empty
     examining pipeline at depth 2 of sets_combined: entry  2 of  3-> empty
     examining pipeline at depth 2 of sets_combined: entry  3 of  3-> empty
%%%%%%%%%%%%%%%%%%%
;
;
;Output:
pipeline for knitted dataset, scaling
 depth 0, type knit

examining pipeline at depth 1 of sets_combined: entry  1 of  3
      depth 1, type align
     examining pipeline at depth 2 of sets: entry  1 of  1-> empty
     examining pipeline at depth 2 of sets_combined: entry  1 of  3-> empty
     examining pipeline at depth 2 of sets_combined: entry  2 of  3-> empty
     examining pipeline at depth 2 of sets_combined: entry  3 of  3-> empty

examining pipeline at depth 1 of sets_combined: entry  2 of  3
      depth 1, type align
     examining pipeline at depth 2 of sets: entry  1 of  1-> empty
     examining pipeline at depth 2 of sets_combined: entry  1 of  3-> empty
     examining pipeline at depth 2 of sets_combined: entry  2 of  3-> empty
     examining pipeline at depth 2 of sets_combined: entry  3 of  3-> empty

examining pipeline at depth 1 of sets_combined: entry  3 of  3
      depth 1, type align
     examining pipeline at depth 2 of sets: entry  1 of  1-> empty
     examining pipeline at depth 2 of sets_combined: entry  1 of  3-> empty
     examining pipeline at depth 2 of sets_combined: entry  2 of  3-> empty
     examining pipeline at depth 2 of sets_combined: entry  3 of  3-> empty
%%%%%%%%%%%%%%%%%%%
=data_knit.sets{1}.dim_list; %list of dimensions of coordinate sets
=; %retrieve paradigm names
show which paradigms contain which stimuli
figure;
;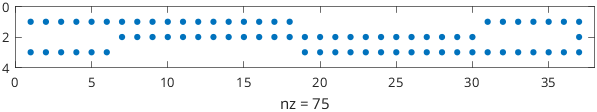
GA: added this line to test if figure saving works... a partial figure should be plotted before this line
=data_knit.sas{1}.nstims;
=data_knit.sas{1}.typenames;
;
;
;
;
;
;
drawnow;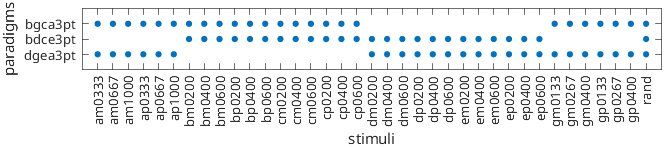
retrieve and plot convergence and scaling
=;
=; %d1 is 1 for standard, 2 for allow scale
=;
figure;
;
=3;
={};
;
;
;
;
;
;
;
;
end
drawnow;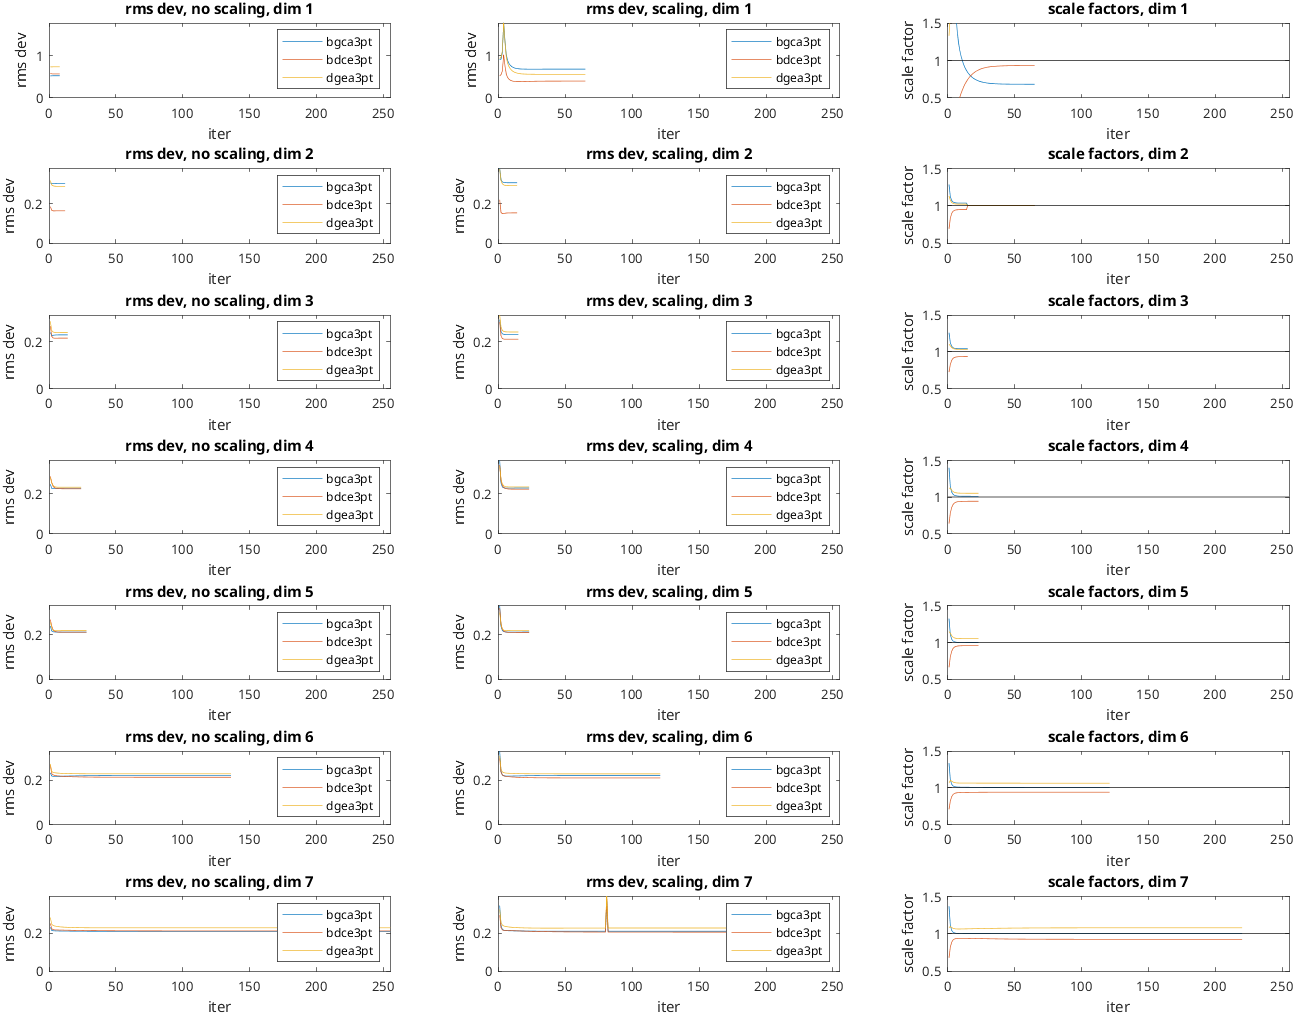
do statistics?
=1;
=nshuffs;
=0; %plot locallyknit and compute stats without allowing scaling between sets
[]=;knit and compute stats, allow scaling between sets;
=aux_stats;
=1;
=1;
[]=;make a combined plot
=figure;
;
;
=aux_knit_stats.knit_stats_setup;
plot non-rescaled analysis
=aux_stats; =aux_knit_stats.knit_stats; =aux_knit_stats.knit_stats_setup;
=fig_handle;
=paradigm_names;
=knit_stats_setup.stimulus_labels;
=2;
=1;
[]=;plot rescaled analysis
=aux_stats_replot; =aux_knit_allowscale_stats.knit_stats; =2; []=;
end %nshuffsOutput:
 number of stimuli missing in dataset   1:   12
 number of stimuli missing in dataset   2:   12
 number of stimuli missing in dataset   3:   12
data table
    25    13    13
    13    25    13
    13    13    25

sa_pooled and data_align are supplied.
knitting  37 stimuli across   3 datasets, dimensions   1  2  3  4  5  6  7
  allow reflection: 1, allow offset: 1, allow scale: 0, normalize scale: 0, rotate to pcs: 0
 calculations with allow_scale=0, if_normscale=0
 set  1: created shuffles for  25 stimuli
 set  2: created shuffles for  25 stimuli
 set  3: created shuffles for  25 stimuli
 creating Procrustes consensus from dim  1 to dim  1 based on component datasets, iterations:    8, final total rms dev per coordinate:  1.05588
 creating Procrustes consensus from dim  2 to dim  2 based on component datasets, iterations:   12, final total rms dev per coordinate:  0.44757
 creating Procrustes consensus from dim  3 to dim  3 based on component datasets, iterations:   14, final total rms dev per coordinate:  0.39385
 creating Procrustes consensus from dim  4 to dim  4 based on component datasets, iterations:   24, final total rms dev per coordinate:  0.39563
 creating Procrustes consensus from dim  5 to dim  5 based on component datasets, iterations:   28, final total rms dev per coordinate:  0.37277
 creating Procrustes consensus from dim  6 to dim  6 based on component datasets, iterations:  136, final total rms dev per coordinate:  0.38140
 creating Procrustes consensus from dim  7 to dim  7 based on component datasets, iterations:  255, final total rms dev per coordinate:  0.37534
 number of stimuli missing in dataset   1:   12
 number of stimuli missing in dataset   2:   12
 number of stimuli missing in dataset   3:   12
data table
    25    13    13
    13    25    13
    13    13    25

sa_pooled and data_align are supplied.
knitting  37 stimuli across   3 datasets, dimensions   1  2  3  4  5  6  7
  allow reflection: 1, allow offset: 1, allow scale: 1, normalize scale: 1, rotate to pcs: 0
 calculations with allow_scale=1, if_normscale=1
 set  1: created shuffles for  25 stimuli
 set  2: created shuffles for  25 stimuli
 set  3: created shuffles for  25 stimuli
 creating Procrustes consensus from dim  1 to dim  1 based on component datasets, iterations:   65, final total rms dev per coordinate:  0.95566
 creating Procrustes consensus from dim  2 to dim  2 based on component datasets, iterations:   14, final total rms dev per coordinate:  0.44842
 creating Procrustes consensus from dim  3 to dim  3 based on component datasets, iterations:   15, final total rms dev per coordinate:  0.39404
 creating Procrustes consensus from dim  4 to dim  4 based on component datasets, iterations:   23, final total rms dev per coordinate:  0.39562
 creating Procrustes consensus from dim  5 to dim  5 based on component datasets, iterations:   23, final total rms dev per coordinate:  0.37207
 creating Procrustes consensus from dim  6 to dim  6 based on component datasets, iterations:  121, final total rms dev per coordinate:  0.37976
 creating Procrustes consensus from dim  7 to dim  7 based on component datasets, iterations:  220, final total rms dev per coordinate:  0.37148
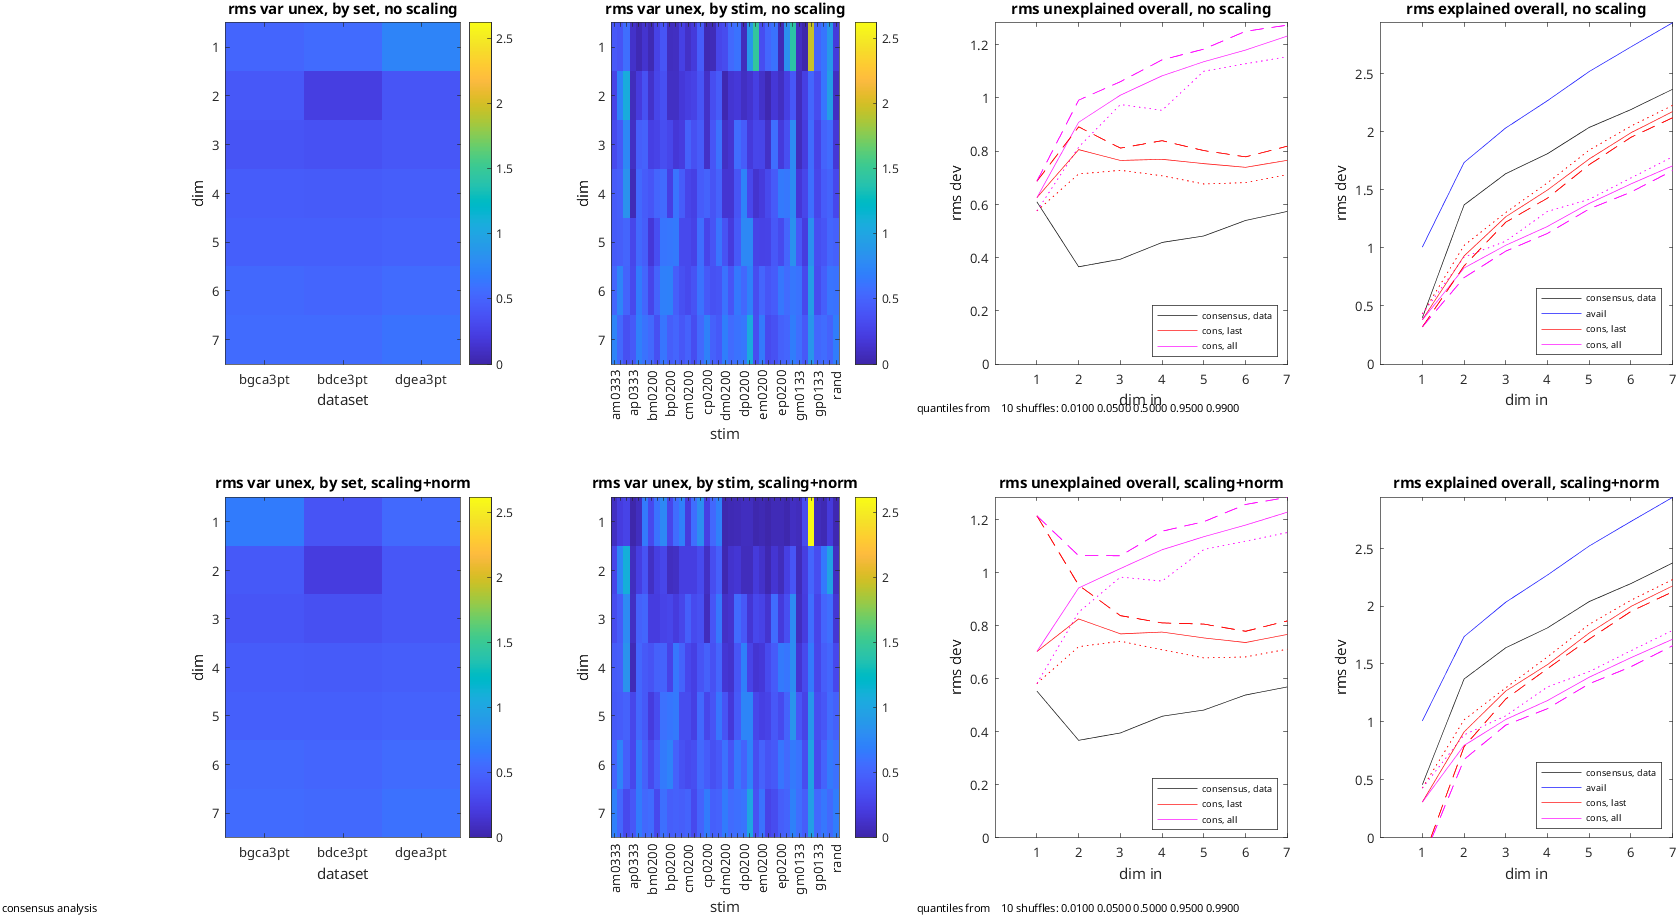
write datasets if requested
=struct;
=0;
=;
end